Three changes after one wrong verdict: the checker reads X Community Notes, tests whether a video shows what a post claims, and stops averaging unproven claims.
This article was researched and drafted with AI, then checked and released by a person before it went live. The illustration is AI-generated. Every factual claim links to its source, so you can verify it yourself.
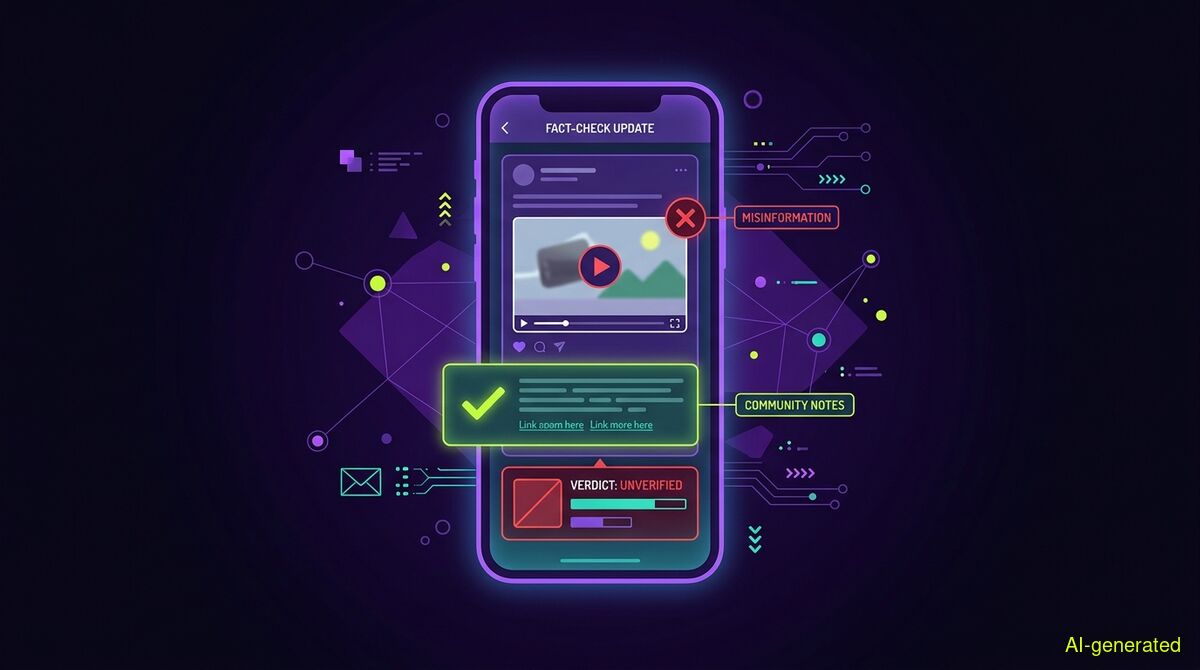
AI-generated illustration. A phone screen showing a post with a video, a note card below it and a verdict panel with a red marker on the footage
wyper Fact-Check now reads the X Community Note attached to a post and feeds it into the check as a source, can test whether a video actually shows what the post's text claims instead of treating footage as decoration, and no longer lets unverifiable statements drag a headline score toward "largely correct". All three changes came from one verdict that was wrong, and the case is described below.
Product updates usually get announced as a list of features. This one started as a mistake, so it is easier to explain it that way.
On 15 September a post on X was checked with wyper. It claimed that a group of people had been robbed, and it carried a doorbell-camera video of a break-in. The check split the post into two statements: the robbery itself, and what the footage showed. The first statement found no reliable source and got a neutral 5 out of 10. The second was rated 10 out of 10, because the video plainly shows a break-in. The headline averaged the two to 7.5 and said "Largely correct".
The post already had a Community Note under it. The note said the video was from a different break-in in 2025 and that no report confirmed the robbery. wyper had loaded the post's data, and the note was sitting in it, unread. Three things were wrong at once, and three changes fix them. They are live in the free wyper web app and in the X bot today; the extension carries them in version 1.9.3, which is going through Chrome Web Store review.
Community Notes are corrections written by X users and shown only when people who usually disagree with each other both rate the note as helpful. They are public and they sit inside the same post data that any checker already downloads. Ignoring them meant ignoring the one correction that was closest to the post.
What changed:
Measured on the case above: before the change, 7.5 and "Largely correct". After it, the first statement dropped to 2 out of 10 with the note as source number one, the headline went to 4 out of 10, "Mixed", and both statements were backed by sources.
A note is not treated as the final word. It is one source with a known author type (X users) and its own citations, and you can open it from the result to judge it yourself. What it can no longer be is invisible.
The second failure was structural. The checker asked "what does this post claim?" and looked for claims in text. A video that carries no caption of its own produced no claim, so nothing tested whether it belonged to the story. Footage that shows a real event can still be attached to the wrong one, and that is the most common form of visual misinformation there is.
For a post on X whose video makes no statement of its own, the extension and the web app now offer three ways forward instead of one:
| Option in wyper | What happens | Cost |
|---|---|---|
| Check the video's origin | The server downloads the clip, runs a reverse search for the same footage across the web and builds an origin report | 4 credits |
| Check the text only | The written claim is checked as before, the video is left alone | 1 check |
| Cancel | Nothing is sent | free |
The origin report is the same one the AI Spotter produces for an uploaded file, so a clip from X gets identical treatment, permissions and refunds as a file you drop in yourself. Measured live on the case: 9 seconds, and the same file found on 6 pages.
Finding the footage elsewhere is not yet an answer, so a second step asks the question that matters: does the video show what the text claims? The comparison gathers the Community Note and the pages it cites, the pages where the reverse search found the footage, a topic search, and a targeted search for the claim itself. A text model then answers only from those sources, with three possible outcomes:
The quote is the guardrail. A "different event" verdict has to carry a verbatim quote of at least eight words that is checked against the source it is attributed to. If the quote cannot be found in that source, the verdict falls back to "open". In testing, the model once named a second incident from a different search result than the one it quoted; that answer was rejected for exactly this reason. On the case above the comparison took 13.6 seconds, drew on 22 sources and returned "different event" with the note's own wording as the evidence. That block is now the first thing you see in the result, marked red, green or yellow, with the note beneath it.
Who needs which: if you only want to know whether a written claim holds, the text-only route is enough and costs one check. If a post leans on footage, check the origin, because that is where the text-only route was blind. Journalists and moderators dealing with breaking events should treat "open" as a real result: it means nobody has tied the footage to the story yet, which is different from the footage being fake.
The third failure was arithmetic. A statement the checker cannot verify gets a neutral 5 out of 10 by design: it means "unknown", not "half right". But a 5 for "unknown" looks identical to a 5 for "partly true", and the headline score averaged both kinds without distinction. One solid 10 next to one unknown 5 produced 7.5 and the words "Largely correct" over a post that was, at best, half checked.
Now:
We ran the new rule over past results: 55 of 207 headline scores of 6.5 or higher would have been lower or absent under it. That is the honest size of the problem, and it is why this change applies to every check, not only to posts with video.
The bot got the same correction from the other side. It used to build its headline from the number alone, so an all-unverified post could come back as "Mixed. Parts hold up, parts do not." above a finding that literally said no reliable sources could be retrieved. It now reads the verdict labels from the pipeline. If nothing could be checked, the reply says "I could not check this against sources." and drops the source list, because a list of loosely related links under that sentence would look like evidence.
Some sentences cannot be checked as a whole and still contain a hard claim. "If the AfD forms a government he might become finance minister, according to WirtschaftsWoche" is speculation wrapped around a checkable attribution: did WirtschaftsWoche report that? The bot used to stop at "I could not check this", which was true and unhelpful.
It now runs a second round only after an empty first one. It extracts the attribution ("according to X", "X reported"), strips the conditional frame and the intent, and checks the resulting statement. On the case that prompted it, the second round found the actual WirtschaftsWoche article and answered that the magazine reported on a speculation, not on an appointment. The reply names the scope in its first line, "checked the WirtschaftsWoche claim", so nobody reads a verdict about one attribution as a verdict about the whole post. The second round is skipped whenever the first one finds something, because every extra round costs money and the honest "could not check" should only be replaced by a real finding.
The rules that were already there still hold. Sources are never filtered by origin, so a Community Note gets no special rank above or below a newsroom or a primary document; it is a source with a visible author type. Two models still check the same evidence and their disagreement is still shown. Every check can still be published to the public proof ledger, and the note block on those pages comes from the server's stored result, not from anything the reader's browser fetched later. Free tiers are unchanged: 5 checks a day in the app and the extension, the bot answers whoever summons it.
One wrong "Largely correct" exposed three gaps: an unread Community Note, a video nobody tested, and an average that treated "unknown" as "half true". wyper Fact-Check now reads the note, checks whether footage matches the claim with a quoted source, and refuses to average what it could not verify. Live in the web app and the bot, in the extension with 1.9.3.
The wyper Fact-Check extension runs these checks on the post itself: truth score, evidence chain, and the date gap that catches recycled footage.
The web app installs to your home screen in one tap. No store, no account.
Already using it? ★★★★★ Rate it on the Chrome Web Store. Reviews decide what others get shown first.
 wyper